Juridia
Multilingual Legal RAG
Fast question answering and search over 100,000+ Arabic and French legal documents.
- <350 ms average query latency
- +18–22% retrieval precision
- 100k+ legal documents
Built with FastAPI
 PostgreSQLQdrantLlamaIndex
 ReactBM25 + cross-encoder
Code is private (company / client work)
Overview
Legal documents written in both Arabic and French are hard to search well: keyword search alone misses relevant texts, and embeddings alone are not precise enough for legal questions.
At Juridia I designed and deployed a production retrieval-augmented generation (RAG) system over more than 100,000 legal documents, built with FastAPI, LlamaIndex, PostgreSQL, and Qdrant, with a search interface offering keyword, semantic, and metadata search.
Combining BM25 with dense retrieval and multilingual embeddings, then reranking with a cross-encoder, improved retrieval precision by 18 to 22% while keeping average query latency below 350 ms. The main lesson: retrieval quality depends on the whole ranking pipeline, not on embeddings alone. The client implementation is private, so only this technical summary is shared.
The question
How can multilingual retrieval stay fast and precise across a large, domain-specific legal corpus?
Key features
- Question answering over 100,000+ Arabic and French legal documents.
- Hybrid retrieval that combines BM25 keyword search with dense multilingual embeddings.
- Cross-encoder reranking, which improved retrieval precision by 18 to 22%.
- A search interface with keyword, semantic, and metadata search.
- Average query latency below 350 ms in production.
How it works
Index
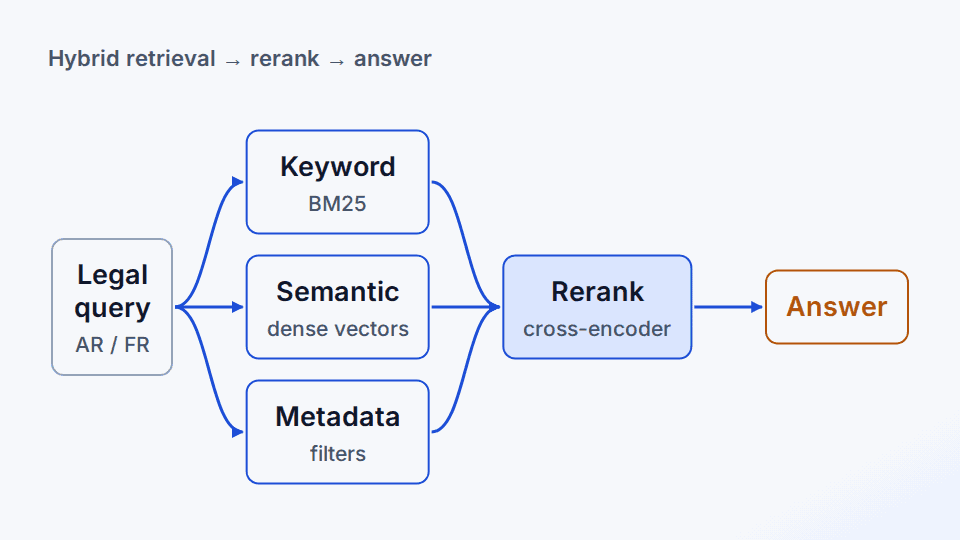
Documents are indexed for both keyword search and multilingual semantic search, using PostgreSQL and the Qdrant vector database.
Hybrid retrieval
A query is matched with both BM25 keyword search and dense semantic search, with metadata filters available.
Rerank
A cross-encoder reorders the candidates so the most relevant passages come first.
Answer and serve
Retrieval-augmented answers are served by a FastAPI service built with LlamaIndex, behind the React search interface.
Tech stack
Production RAG and search API
Database
Vector database for multilingual embeddings
RAG framework
Search interface
BM25 + cross-encoder
Hybrid keyword search and reranking
What I learned
- Retrieval quality depends on the whole ranking pipeline, not embeddings alone
Limitations
- Client implementation is private; only a portfolio-level technical summary is shared